Dedicated RTX 2080 Ti for ComfyUI: A Practical Local Baseline
An idle GPU with a useful job
Running a local AI stack often leads to resource contention. My server houses three GPUs: an RTX 2080 Ti with 11 GB of VRAM, an RTX 3090 Ti, and an RTX 3090. The two 3090-class cards are already committed to a local Qwen chat service. This left the 2080 Ti sitting idle, but the previous ComfyUI installation was configured to see all available GPUs. This configuration created a risk: if the image generation service started, it could compete with the chat service for memory and compute resources.
On September 24, 2026, I wanted to isolate the image generation workload. The goal was simple: assign ComfyUI exclusively to the 2080 Ti and verify that the chat services remained untouched. The old ComfyUI container was already stopped before this work began. I inspected its old all-GPU configuration, which also included a broken optional Manager extension. We then started a new restricted container. This new setup uses a fixed set of installed dependencies, meaning boot no longer installs or upgrades packages. Model files and generated images are stored separately from the application image.
Keeping the GPU workloads separate
The key step was explicit GPU assignment. By using stable GPU identity, the new ComfyUI container was bound strictly to the 2080 Ti. Verification confirmed that exactly one GPU was visible to the process. This isolation prevents the ComfyUI process from using the chat GPUs. However, CPU, RAM, storage, and power are still shared resources. We verified that chat container identities and sampled GPU memory allocations remained unchanged. No chat latency test was performed, so we cannot claim that chat responsiveness is guaranteed or that the chat service cannot be starved of any resources. We simply confirmed that the GPU isolation worked as intended.
Testing a real image workflow
For the baseline test, we used the Stable Diffusion XL base 1.0 model. The workflow was kept minimal: one 1024 by 1024 image, batch size 1, 25 steps, using the DPM++ 2M sampler with a Karras scheduler. The test prompt depicted a red sailboat on a calm lake with mountains and morning light. The resulting image was visually coherent, not black or corrupt, confirming that CUDA access and model loading were functioning correctly.
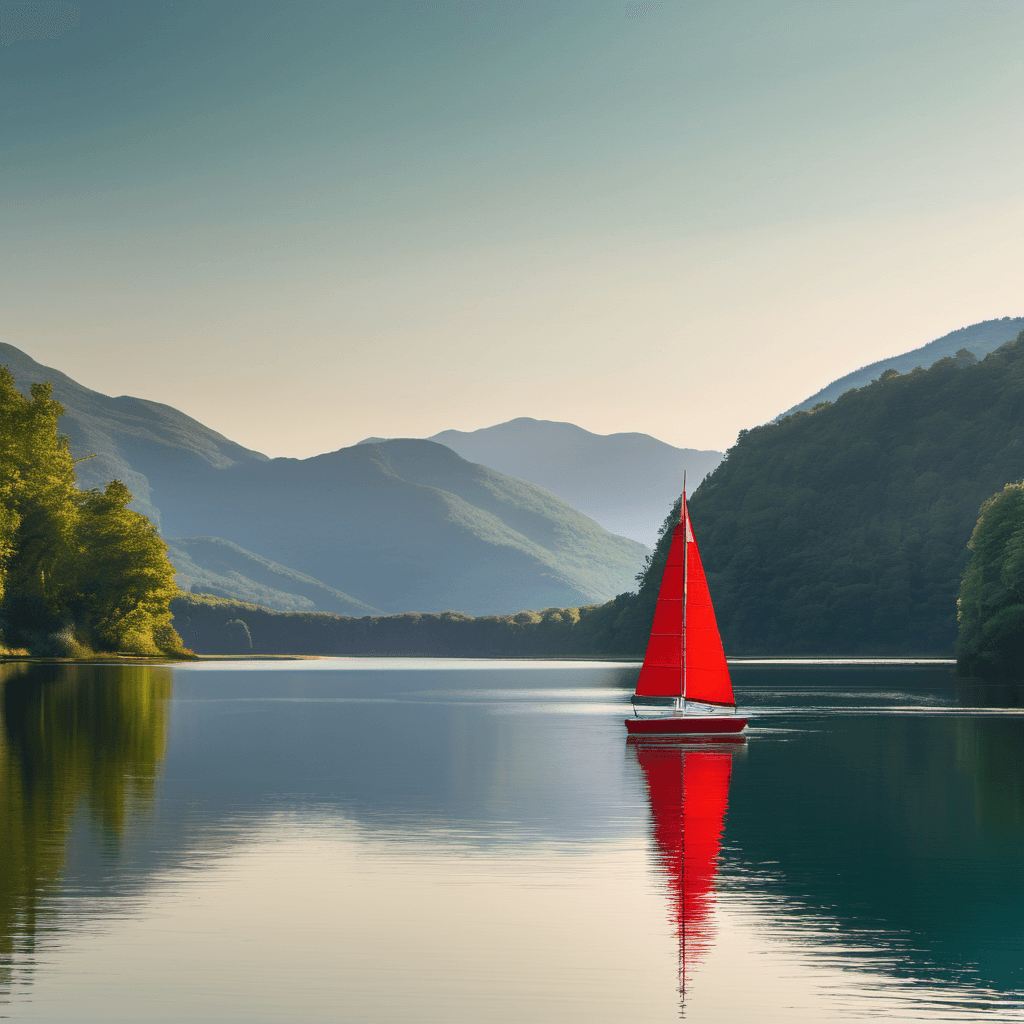
The actual SDXL baseline output: 1024 × 1024 pixels, 25 steps, generated on the RTX 2080 Ti.
The performance metrics were straightforward. One observed end-to-end API test completed in 18.49 seconds, including workflow completion and polling. Server execution time was approximately 17.36 seconds. This is a single observed data point, not a warmed benchmark or a guaranteed production average. It establishes a working baseline, but it does not prove production reliability or general stability. We verified startup, CUDA access, a real generation, and a service restart, but we did not perform a host reboot test.
Understanding the memory headroom
Resource usage was also monitored. Peak observed VRAM was 7,266 MiB, which is about 7.1 GiB. This was sampled every three seconds, a method that can miss instantaneous peaks. While this leaves headroom on the 11 GB card, it is not a configured cap. ComfyUI automatically manages VRAM, reserving 1 GB as a headroom setting rather than a hard memory quota. It can use more memory when workflows require it and offload model components to RAM as needed. More complex workflows are not yet benchmarked, so this baseline does not guarantee performance for heavier tasks.
Starting with the hardware already here
The broader lesson is about starting with what you have. We reused existing hardware, requiring no new purchases. We separated competing workloads to prevent GPU resource contention. We established a small, measurable workflow before attempting to enable custom extensions or heavier features. A working web page does not prove that image generation works; only a verified, isolated test does. This baseline gives us a functional foundation to build upon, knowing that the image generation service is isolated from the chat GPUs and capable of generating coherent images.